A description of the possible cluster states:
ST_INIT: cluster configured and down
ST_JOINING: node joining the cluster
ST_VOTING: Inter-node decision state for an event
ST_RP_RUNNING: cluster running recovery program
ST_BARRIER: clstrmgr waiting at the barrier statement
ST_CBARRIER: clstrmgr is exiting recovery program
ST_UNSTABLE: cluster unstable
NOT_CONFIGURED: HA installed but not configured
RP_FAILED: event script failed
ST_STABLE: cluster services are running with managed resources (stable cluster) or cluster services have been "forced" down with resource groups potentially in the UNMANAGED state (HACMP 5.4 only)
Wednesday, June 11, 2014

Wednesday, June 4, 2014
Monday, February 3, 2014
Cleaning up a shared memory segment which won't go away with ipcrm
I have seen this happening when we run DB2 on AIX. Sometimes a stopped instance won't release the shared memory segment, not even with ipcrm. Here's what can be done under this situation:
1) Use the new -S option on ipcs to obtain the shared memory segment ID.
# ipcs -mS
m 131075 0x00001a4c --rw------- root system
SID :
0x2b85
2) Verify that the svmon command is installed on the system. If not,
install from the AIX installation CDs.
$ lslpp -l perfagent.tools
3) Use the svmon command to find all processes attached to the shared
memory segment.
# svmon -S 0x2b85 -l
Vsid Esid Type Description LPage Inuse Pin Pgsp Virtual
2b85 3 work shared memory segment - 656 0 0 656
pid(s)=10862
This shared memory segment has only one process attached.
To remove this shared memory segment, you must first kill the process that is attached to the segment.
# kill 10862
# ipcrm -m 131075
Memory utilisation of processes in AIX
For memory information, we use the command svmon.
svmon shows the total usage of physical and paging memory.
Command to display top ten processes and users
svmon -P -v -t 10 | more
Displaying top CPU_consuming processes:
ps aux | head -1; ps aux | sort -rn +2
Displaying top memory-consuming processes:
ps aux | head -1; ps aux | sort -rn +3 | head
Displaying process in order of priority:
ps -eakl | sort -n +6 | head
Displaying the process in order of time
ps vx | head -1;ps vx | grep -v PID | sort -rn +3
Displaying the process in order of real memory use
ps vx | head -1; ps vx | grep -v PID | sort -rn +6
Displaying the process in order of I/O
ps vx | head -1; ps vx | grep -v PID | sort -rn +4
Sunday, November 17, 2013
DLPAR not doing it for you anymore?
Based on my experience, the most common issue that prevents DLPAR operations from working are network problems. Before diving into the deep end and trying to debug RSCT, it’s always best to start with the basics. For example, can you ping the HMC from the LPAR? Can you ping the LPAR from the HMC? If either of these tests fails, check the network configuration on both components before doing anything else.
On the HMC check the network settings first e.g.
Click on HMC Configuration and then Customize Network Settings.
– Verify the IP address, netmask, default gateway, network routes, DNS server are all set correctly.
– Check the LPAR communications box in HMC configuration screen for LAN adapter that is used for HMC-to-LPAR communication.
– By the way, unlike POWER4 systems, LPARs on POWER5 and POWER6 systems do not depend on host name resolution for DLPAR operations.
Check routing on the LPAR and the HMC.
– Use ping and the HMC’s Test Network Connectivity task to verify the LPAR and the HMC can communicate with each other.
If you check the network and you are happy that the LPAR and the HMC can communicate, then perhaps you need to re-initialise the RMC subsystems on the AIX LPAR. Run the following commands:
# /usr/sbin/rsct/bin/rmcctrl –z
# /usr/sbin/rsct/bin/rmcctrl –A
# /usr/sbin/rsct/bin/rmcctrl –p
Wait up to 5 minutes before trying DLPAR again. If DLPAR still doesn’t work i.e. the HMC is still reporting no values for DCaps, and the IBM.DRM subsystem still won’t start, try using the recfgct command.
hscroot@hmc1:~> lspartition -dlpar
.....
<#5> LPAR:<24 192.168.1.15="">
Active:<1>, OS:
.....
# /usr/sbin/rsct/install/bin/recfgct
Wait 5 minutes. This should resolve your DLPAR issue. The IBM.DRM subsystem should now be active and there should be good (non-zero) values for DCaps:
# lssrc -g rsct_rm
Subsystem Group PID Status
IBM.DRM rsct_rm 6881300 active
IBM.CSMAgentRM rsct_rm 7274530 active
IBM.ServiceRM rsct_rm 6029480 active
IBM.AuditRM rsct_rm 6357058 active
IBM.ERRM rsct_rm 4456566 active
IBM.LPRM rsct_rm 6946986 active
hscroot@hmc1:~> lspartition -dlpar
....
<#5> LPAR:<24 192.168.1.15="">
Active:<1>, OS:
....
Only run the rmcctrl and recfgct commands if you believe something has become corrupt in the RMC configuration of the LPAR. The fastest way to fix a broken configuration or to clear out the RMC ACL files after cloning (via alt_disk migration) is to use the recfgct command.
These daemons should work “out of the box” and are not typically the cause of DLPAR issues. However, you can try stopping and starting the daemons when troubleshooting DLPAR issues.
The rmcctrl -z command just stops the daemons. The rmcctrl -A command ensures that the subsystem group (rsct) and the subsystem (ctrmc) objects are added to the SRC, and an appropriate entry added to the end of /etc/inittab and it starts the daemons.
The rmcctrl –p command enables the daemons for remote client connections i.e. from the HMC to the LPAR and vice versa.
If you are familiar with the System Resource Controller (SRC) you might be tempted to use stopsrc and startsrc commands to stop and start these daemons.
Do not do it; use the rmcctrl commands instead.
If /var is 100% full, use chfs to expand it. If there is no more space available, examine subdirectories and remove unnecessary files (for example, trace.*, core, and so forth). If /var is full, RMC subsystems may fail to function correctly.
The polling interval for the RMC daemons on the LPAR to check with the HMC daemons is 5-7 minutes; so you need to wait long enough for the daemons to start up and synchronize.
The Resource Monitoring and Control (RMC) daemons are part of the Reliable, Scalable Cluster Technology (RSCT) and are controlled by the System Resource Controller (SRC). These daemons run in all LPARs and communicate with equivalent RMC daemons running on the HMC. The daemons start automatically when the operating system starts and synchronize with the HMC RMC daemons.
The daemons in the LPARs and the daemons on the HMC must be able to communicate over the network for DLPAR operations to succeed. This is not the network connection between the managed system (FSP) and the HMC; it is the network connection between the operating system (AIX) in each LPAR and the HMC.
Note: Apart from rebooting, there is no way to stop and start the RMC daemons on the HMC.
Friday, October 25, 2013
removed the large file, but still the file is open and holding the space.
fuser -dV
-d Reports on any open files which have been unlinked (deleted) from the file system containing File. When used in conjunction with the -V flag, it also reports the inode number and size of the deleted file.
-V - verbose output
Thursday, July 18, 2013
AIX Print Commands
qchk -q To display the default q
qchk -P lp0 To display the status of the printer lp0
qchk -# 123 To display the status of job number 123
qchk -A To display the status of all queues
qcan -x 123 To cancel the print job 123
qcan -X -P lp0 To cancel all jobs submitted to lp0
qpri -#570 -a 25 To change the priority of the job to 25
qhld # 569 To hold the job 569
qhld -r -#569 To remove holding from 569
qmov -m lpa -#11 To move the job 11 to queue lpa
enable psq To enable queue psq
disable psq To disable queue psq
cancel -#111 To cancel job 111
lpstat To display the status all queues
lpstat -p lp0 To display the status of print queue lp0
lpstat -u root To display the jobs submitted by user root
lpq -P lp0 To display the status of queue lp0
last To list all the records in the /var/adm/wtmp file
last |grep shutdown To show the shutdown sessions
uptime (w -u ) To show how long the system has been up
Sunday, June 2, 2013
Stopping HACMP cluster services without stopping applications
You can stop cluster services without stopping services
and applications.
To stop cluster services without stopping your applications:
- Enter the fastpath smit cl_admin or smitty hacmp.
- Select System Management (C-SPOC) and press Enter.
- Select Manage HACMP Services > Stop Cluster Services and press Enter.
- Choose Unmanage resource groups.
No matter what type of resource group you have, if you
stop cluster services on the node on which this group is active and
do not stop the application that belongs to the resource group,
HACMP puts the group into an UNMANAGED state and keeps the application
running according to your request.
The resource group that contains
the application remains in the UNMANAGED state (until you tell HACMP
to start managing it again) and the application continues to run.
While in this condition, HACMP and the RSCT services continue to run,
providing services to ECM VGs that the application servers may be
using.
You can tell HACMP to start managing it again either
by restarting Cluster Services on the node, or by using SMIT to move
the resource group to a node that is actively managing its resource
groups. See Starting HACMP cluster services with manually managed
resource groups for more information.
If you have instances
of replicated resource groups using the Extended Distance capabilities
of the HACMP/XD product, the UNMANAGED SECONDARY state is used for
resource groups that were previously in the ONLINE SECONDARY state.
You
can view the new states of the resource groups using the cluster utilities clstat and clRGinfo .
You
cannot dynamically reconfigure (DARE) the cluster configuration while
some cluster nodes have resource groups in the unmanaged state.
Warning about placing resource groups in an unmanaged
state
When you stop cluster services on a node and place
resource groups in an UNMANAGED state, HACMP stops managing the resources
on that node. HACMP will not react to the individual resource failures,
application failures, or even if the node crashes.
Because the
resources of a system are not highly available when you place resource
groups in an unmanaged state, HACMP prints a message periodically
that the node has suspended managing the resources.
The ability
to stop a node and place resource groups in an UNMANAGED state is
intended for use during brief intervals for applying updates or for
maintenance of the cluster hardware or software.
When you may
want to stop HACMP cluster services without stopping applications
When
you may want to stop HACMP cluster services without stopping applications
In
general, HACMP cluster services are rarely the cause of problems in
your configuration. However, you may still want to stop HACMP cluster
services on one or more nodes, for example, while troubleshooting
a problem or performing maintenance work on a node.
Also, you
may want to stop HACMP cluster services from running without disrupting
your application if you expect that your activities will interrupt
or stop applications or services. During this period of time, you
do not want HACMP to react to any planned application "failures" and
cause a resource group to move to another node. Therefore, you may
want to remove HACMP temporarily from the picture.
Friday, August 20, 2010
Command to delete file by inode number
To find the inode number:
Output:
$ ls -ilOutput:
781956 drwx------ 3 viv viv 4096 2006-01-27 15:05 gconfd-vivCommand to delete file by inode number:
781964 drwx------ 2 viv viv 4096 2006-01-27 15:05 keyring-pKracm
782049 srwxr-xr-x 1 viv viv 0 2006-01-27 15:05 mapping-viv
781939 drwx------ 2 viv viv 4096 2006-01-27 15:31 orbit-viv
781922 drwx------ 2 viv viv 4096 2006-01-27 15:05 ssh-cnaOtj4013
$ find . -inum 781922 -exec rm -i {} \;
Sunday, August 15, 2010
Solaris Run Level
Default Solaris Run Level
- init S : Single user state (useful for recovery)
- init 0 : Access Sun Firmware ( ok> prompt)
- init 1 : System administrator mode
- init 2 : Multi-user w/o NFS
- init 3 : Multi-user with NFS
- init 4 : Unused
- init 5 : Completely shutdown the host (like performing a power-off @ OBP) [ thanks to Marco ]
- init 6 : Reboot but depend upon initdefault entry in /etc/inittab
To find out current runlevel use who command:
$ who -r
Wednesday, August 4, 2010
To add a new disk and migrate the new disk and remove old
There are many ways to do. I have preferred this way.
- cfgmgr
- extendvg vgname newdisk
- mirrorvg vgname newdisk
- unmirrorvg vgname olddisk
- reducevg vgname olddisk
- rmdev –Rdl olddisk
- cfgmgr
- extendvg vgname newdisk
- migratepv olddisk newdisk
- rmdev –Rdl olddisk
Monday, August 2, 2010
JFS2 MAJOR MINOR DEVICE NUMBER
errpt command show the error message complaining about filesystem is full (df command shows some 10 filesystems is being 100% used). . The detailed report gives the major/minor device number: 000A 000F.
The characters: 000A 000F on the message are hexadecimal numbers. convert them to decimal numbers( 10 and 15) respectively. So, go to directory /dev and issue the command:
For instance,
#cd /dev
#ls -al | grep 10, 15
crw-rw---- 1 root system 10, 15 Apr 22 08:27 rtemplv
brw-rw---- 1 root system 10, 15 Apr 22 08:27 templv
Look on the 5th and 6th columns for an entry such as: 10, 15 and that will be the device with the issue
From this we can come to know which filesystem is full.
Questions and suggestions are welcome. Thanks
Monday, July 26, 2010
Procedure to grow the veritas filesystem in solaris Environment
1. Once the LUN is added, we need to configure the new LUN
devfsadm –c disk (will configure the new LUN)
then label the disk by executing the command format, it will prompt to label the disk (enter yes)
2. Once the disk is configured we have to initialize the disk in veritas
vxdisksetup –i diskname
for eg. vxdisksetup –i c0t1234567888d94
3. Now add the disk to the diskgroup in veritas
vxdg –g dgname adddisk mediaaccessname=diskname
for eg. vxdg –g oradg adddisk ora001=c0t1234567888d94
4. To grow the filesystem
vxresize –g dgname volumename size mediaaccessname.
for eg. vxresize –g oradg oravol +100M ora001
Questions and suggestions are welcome. Thanks
devfsadm –c disk (will configure the new LUN)
then label the disk by executing the command format, it will prompt to label the disk (enter yes)
2. Once the disk is configured we have to initialize the disk in veritas
vxdisksetup –i diskname
for eg. vxdisksetup –i c0t1234567888d94
3. Now add the disk to the diskgroup in veritas
vxdg –g dgname adddisk mediaaccessname=diskname
for eg. vxdg –g oradg adddisk ora001=c0t1234567888d94
4. To grow the filesystem
vxresize –g dgname volumename size mediaaccessname.
for eg. vxresize –g oradg oravol +100M ora001
Questions and suggestions are welcome. Thanks
Saturday, July 24, 2010
To disable telnet/rexec services on Aix servers
1. Take a backup of /etc/inetd.conf(before editing the file better to to a backup)
2. Edit /etc/inetd.conf file and comment out telnet,rexec, services
vi /etc/inetd.conf
comment out (enter # ) the telnet, rexec services
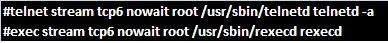
3. Restart the inetd service
refresh -s inetd
cp -p /etc/inetd.conf /etc/inetd.conf_backup
2. Edit /etc/inetd.conf file and comment out telnet,rexec, services
vi /etc/inetd.conf
comment out (enter # ) the telnet, rexec services

3. Restart the inetd service
refresh -s inetd
Sendmail configuration
1. cp -p /etc/sendmail.cf /etc/sendmail.cf.backup
2. vi /etc/sendmail.cf
3. Search for #DSmailer:relayhostname
4. Add hostname
5. refresh -s sendmail
6. echo " hi " | mail -s " testmail" yourmailid@zzz.com
2. vi /etc/sendmail.cf
3. Search for #DSmailer:relayhostname
4. Add hostname
5. refresh -s sendmail
6. echo " hi " | mail -s " testmail" yourmailid@zzz.com
Subscribe to:
Posts (Atom)